Leaderboard
The TrueHuman Claims Benchmark
Can a frontier model handle a liability claim end to end, the way an experienced adjuster would? Long-horizon claims work, graded on an expert rubric. First release, November 2026.
766
Rubric criteria, each a yes or a no an adjuster would check
430 days
Of simulated time on the longest claim, worked in a single run
3 models
From Anthropic, OpenAI and Google, on the same claims and the same grader
How to read the board
Score
The share of the rubric’s points a model earned on a claim, averaged over every claim, from 0 to 100.
Runs
Claude Opus 5.5 ran every claim 3 times at each level, the other models once. The range after a score is its 95% confidence interval, given with 3 runs of every claim.
Critical error
A mistake an adjuster could not let stand, such as admitting fault to the other side or paying above the limit. It caps the claim at 40, whatever else the model got right.
Guided and Hard
Guided gives the model the house rules; Hard gives none. The two boards are never averaged.
October 2026, every model at high reasoning effort: Claude Opus 5.5 through Claude Code, GPT-6.1 Sol through Codex, Gemini 4 Argon through Antigravity. Through Antigravity a long document reaches the model in pages, and the model asks for each next page; the other models get it whole. A technical report will follow.
How a claim is graded
One claim, three layers.
-
01
The claim
Police reports, medical records, demands and lawsuits reach the adjuster over simulated months, as they would on a real desk.
-
02
What the model does
It works the claim as the adjuster, one action at a time: it requests records, sets reserves, writes to the parties, negotiates and closes. In one run from the benchmark, 85 actions over 260 days.
-
03
The adjuster’s key
A program checks what was done, by when and for how much. Two model judges from two labs read the letters and notes against the rubric.
766
Rubric criteria, 66 to 92 per claim: what was done, by when, and for how much.
99.96%
Agreement of the two model judges with 4,833 answers decided in advance.
95% CI
On the scores from 3 runs of every claim: Claude Opus 5.5 so far. Guided and Hard reported apart.
100 / 18
Sanity checks: following the expert’s answers scores 100 on every claim; doing nothing scores 18 on average, 23 at most.
The expert check
Our rubric is checked against a real adjuster’s own decisions.
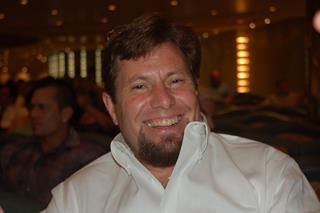
Earl Stigler
Texas claims adjuster for more than 20 years · more than 12,000 claims adjusted
Earl checks our grading claim by claim, point by point: what the adjuster had to do, by when, and for how much. Where he and a rule disagree, the rule is rewritten.
He has handled auto liability, commercial and residential claims, and has served as an appraiser, umpire and expert witness in Texas.
For labs
Evaluation and training data for claims agents
Long-horizon claims environments with an expert-checked rubric, for evaluation and reinforcement learning. Pricing on request.
Evaluate
Private evaluations
Run your model on held-out claims, through an API, before launch. Same scoring as the public board: a program plus two model judges.
You see an average over 3 runs. The claims, the rubric and the answer key stay secret.
Train
RL environment
The same engine and grader, for training. Public claims at two levels, packaged as Harbor tasks, scored with your own judges.
License
Licensed task sets
Tasks from expert-checked claims, with their rubrics, licensed with the grader so scores stay comparable.
For insurers
Test an AI claims tool against your own guidelines
Bring your claims guidelines; we score the tool on the same claims and grader.
Questions
Frequently asked questions
Whether a model can handle a liability claim as the adjuster, end to end: from first notice to settlement, through tools, over simulated weeks and months, graded the way an experienced adjuster would grade it.
Claude Opus 5.5 (Anthropic), GPT-6.1 Sol (OpenAI) and Gemini 4 Argon (Google), on the same claims and grader. Claude Opus 5.5 ran every claim 3 times at both levels, GPT-6.1 Sol once at both levels, and Gemini 4 Argon once at Hard; its Guided runs are next.
A program checks actions, dates and amounts. Two model judges answer yes-or-no rubric questions about each letter and note: 766 criteria in all. Six areas add up to 100: actions and deadlines, reserves, settlement, red flags, closing and conduct. A critical error caps the claim at 40.
Guided gives the model the house rules. Hard does not. The two are reported separately and never averaged.
The claim’s score is capped at 40, whatever else the model got right, and the run counts under Critical errors on the board.
They are never published and never ship in the package. A lab’s model plays them through our API, one call at a time, and the lab sees only an average score over 3 runs: never a single run’s grade, the rubric or the answer key.
Earl Stigler, a Texas claims adjuster for more than 20 years, with more than 12,000 claims adjusted. He checks our grading claim by claim; where he and a rule disagree, the rule is rewritten.
Yes: private evaluations before launch, the RL environment with the same engine and grader, and licensed task sets. Pricing on request.
Contact
Run your model on held-out claims.
Private evaluations, the RL environment and licensed task sets. Pricing on request.
Or write to help@mytruehuman.com
Interested in
We use these details only to answer you.
Thank you. We will write back soon.
Your email app has opened with the message; send it from there.